Search
Featured Programs


 News


 15/09/2026 15:19
 Editor:
Tomasz Koper


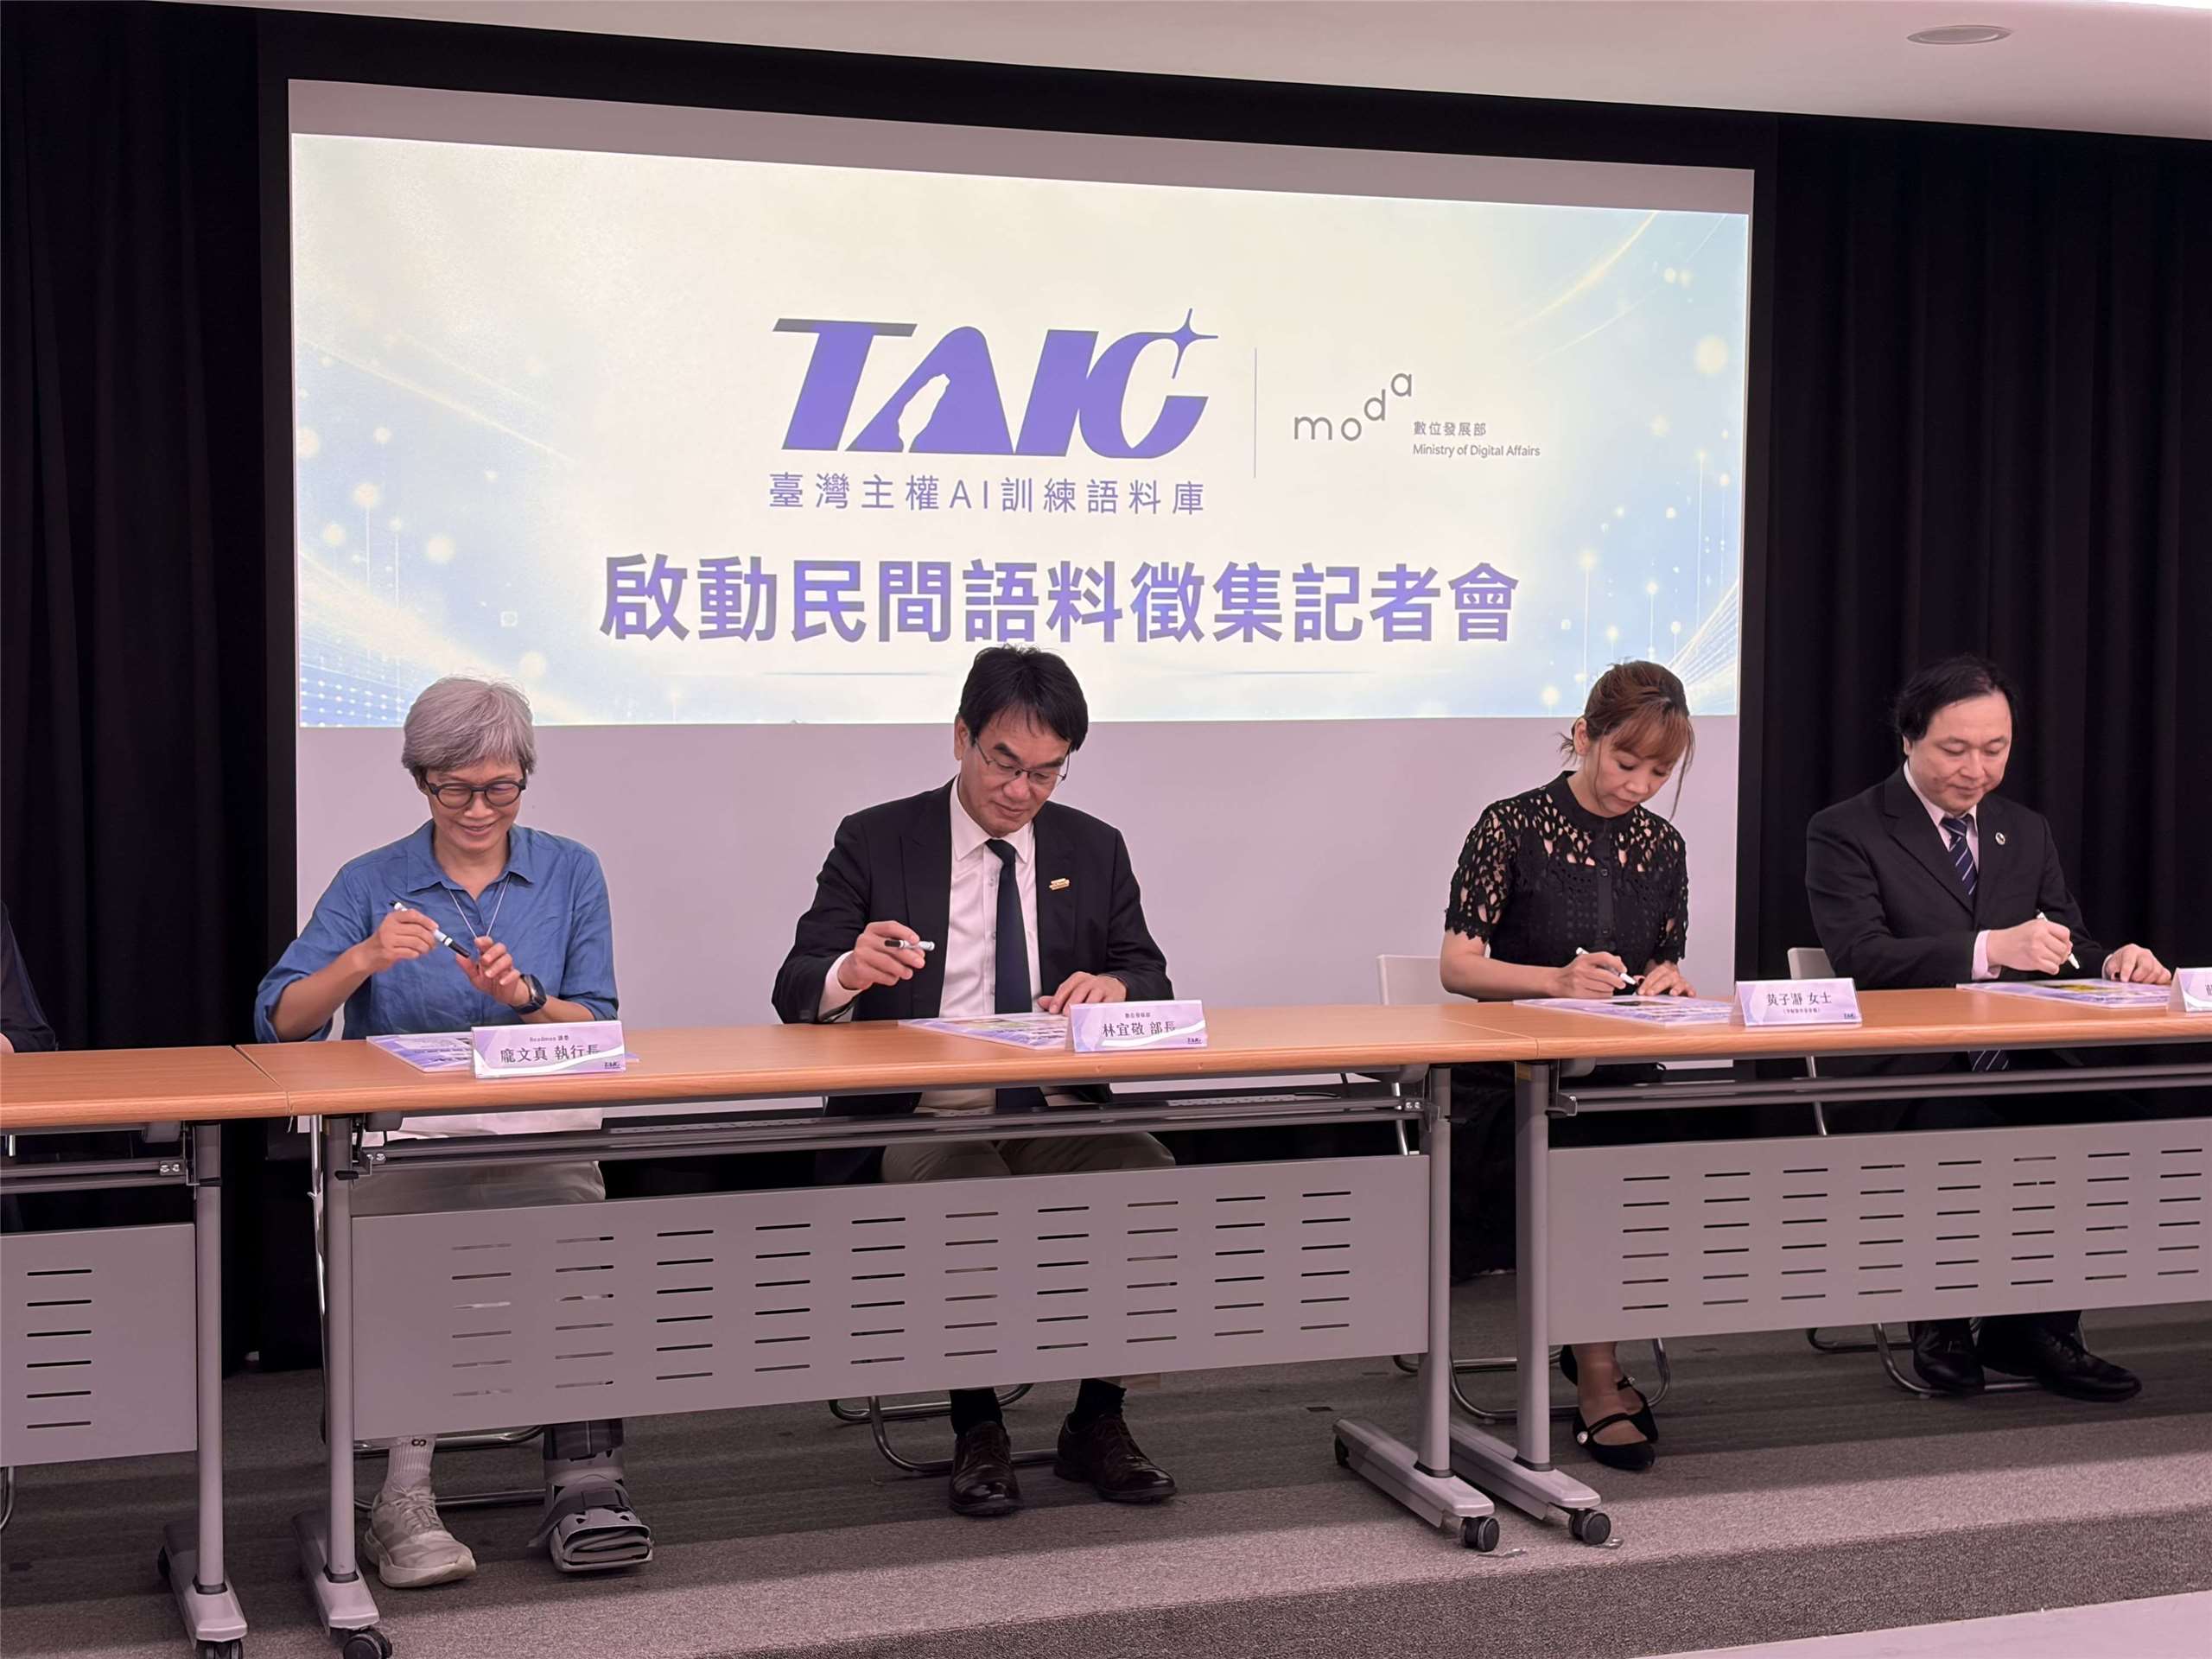
The Digital Ministry has launched a new language corpus collection initiative, encouraging the public to contribute data and written works reflecting Taiwanese perspectives, to be used in training AI language models. The initiative will make this data available to artificial intelligence developers worldwide, with the goal of helping Taiwan’s perspective reach a global audience through AI.
Digital Minister Lin Yi-jing (林宜敬) said at a press conference launching the initiative that major international AI models are trained using large volumes of internet text originating from China. This potentially causes the models to reflect Chinese perspectives on topics like history and politics.
Lin said that discussions on regulating the use of copyrighted content in AI model training are ongoing, and could go on for several years before a consensus is reached. Taiwan, however, cannot afford to wait this long or its perspective may struggle to reach the world, given the rapid pace of AI development. For this reason, the government is advancing the corpus collection initiative, aiming to increase the amount of training data that reflects Taiwanese points of view.
Lin explained that in addition to releasing government-owned works, the initiative will also collect materials from the public and make them available to AI development teams both in Taiwan and around the world. He encouraged authors to make their works available, so that their perspectives may be able to influence the world.
The Digital Ministry added that authors and publishers will be able to withdraw authorization in the future at any time. It said Minister Lin, being a writer himself, was among the first to allow his works to be included in the corpus, in hopes of encouraging more creators to participate.
 /
 Experts say China spying case ‘tip of iceberg’ of Beijing’s transnational repression